Methodology
Architecture Design
SteerVTE augments a frozen video diffusion transformer with a
Text Context Adapter that jointly encodes positional, stylistic, and glyph-level cues.
- Mask-guided positional conditioning uses a spatiotemporal mask to localize edits while preserving background fidelity.
- Native-resolution VLM style encoding preserves typographic attributes such as stroke thickness, spacing, and aspect ratio by tokenizing images at original aspect ratios.
- Dual-granularity glyph control injects line-level layout priors and character-level stroke priors from an OCR network, both rendered in a neutral font to expose content while leaving style to the VLM encoder.
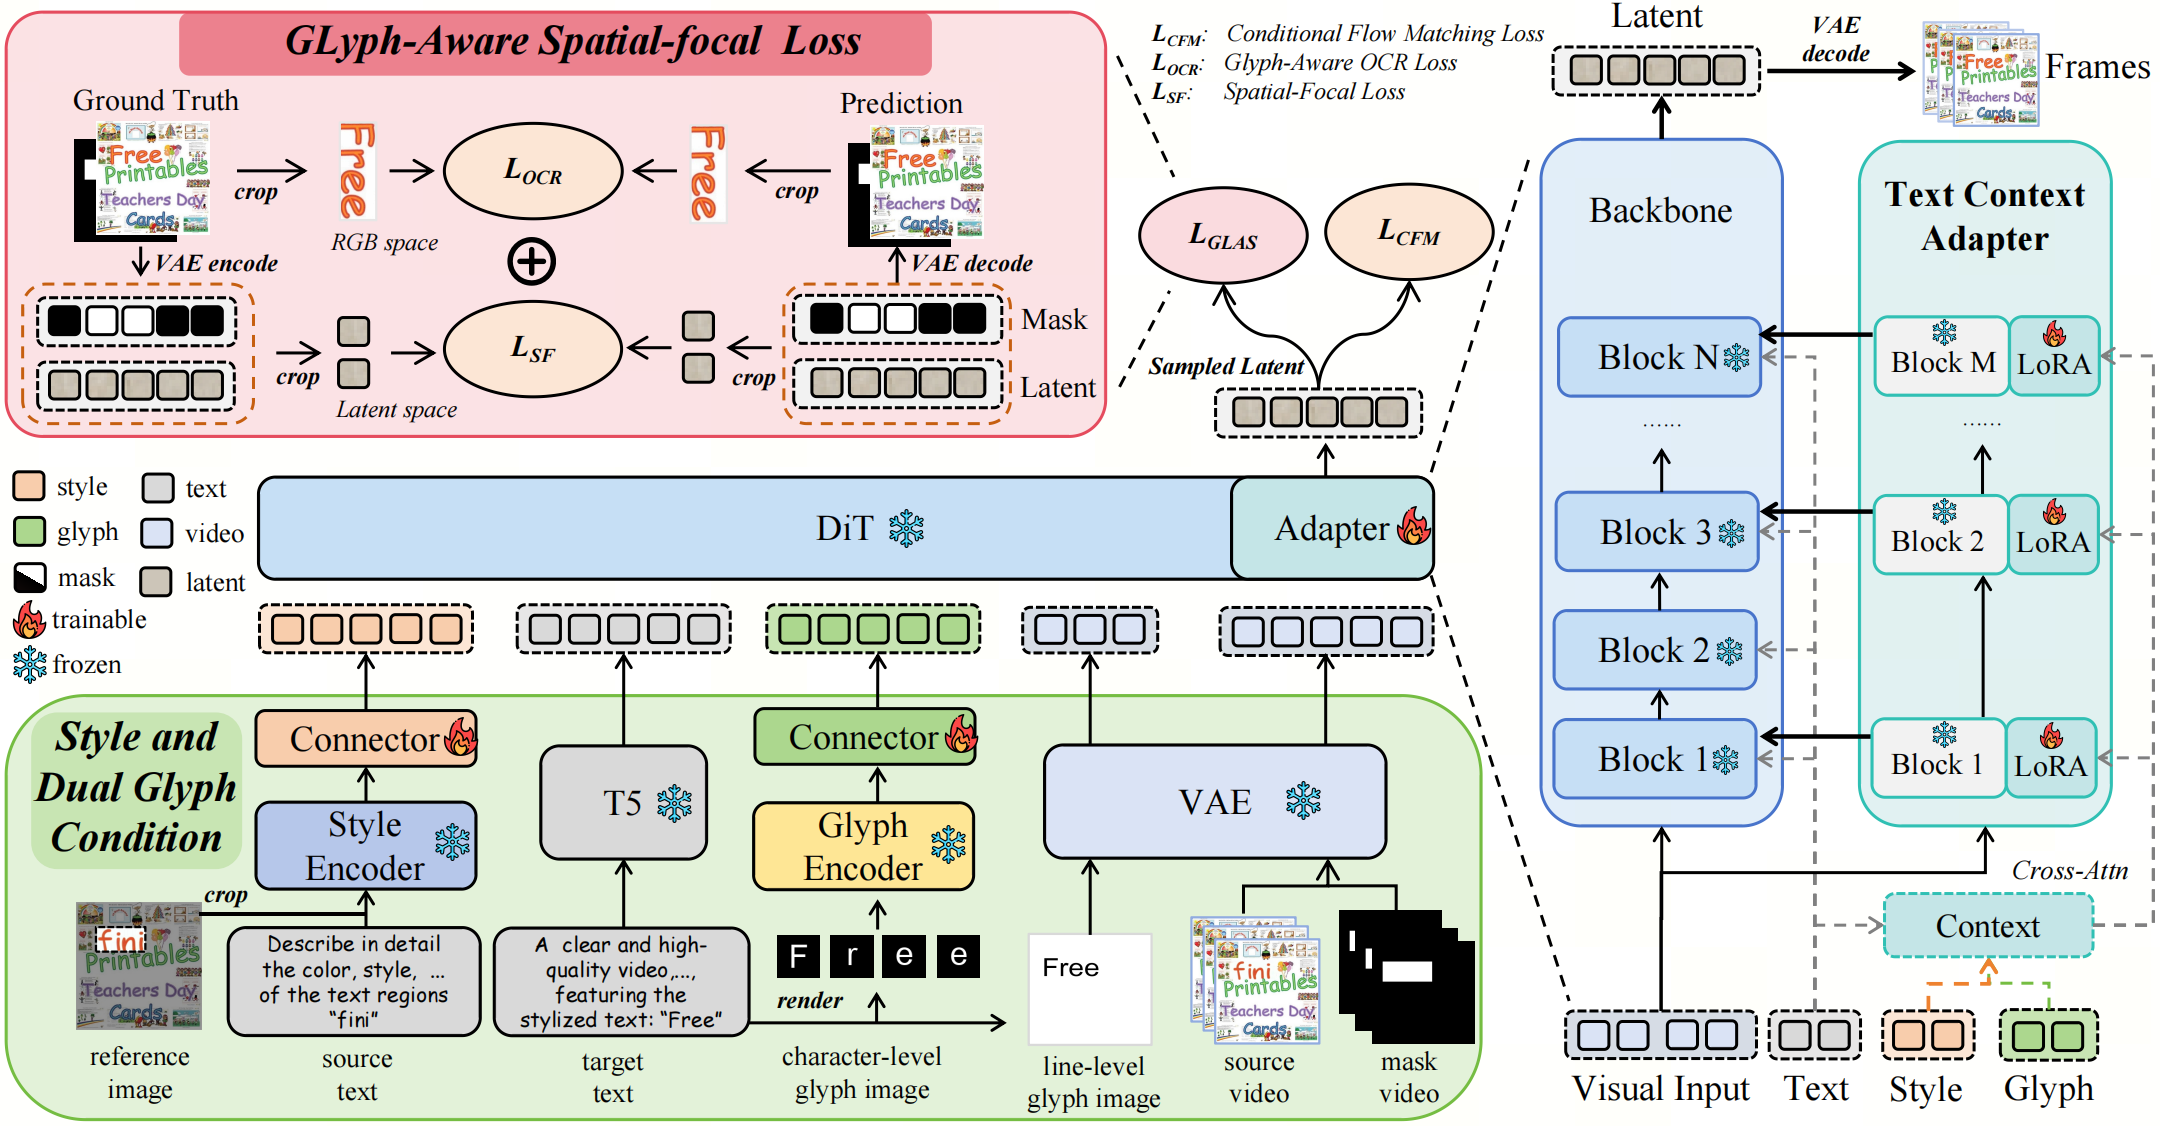
Glyph-Aware Spatial-Focal (GLAS) Loss
Standard flow matching treats all spatial locations equally, causing text-region gradients to be suppressed by backgrounds and lacking inductive bias toward character topology. We propose the GLAS Loss, a dual-space paradigm:
- Spatial-Focal Loss reweights the objective with a focal map from the mask, concentrating optimization on text regions.
- Glyph-Aware OCR Loss imposes pixel-space supervision via an OCR recognizer, enforcing stroke-level fidelity and character-level recognizability.
Training Dataset
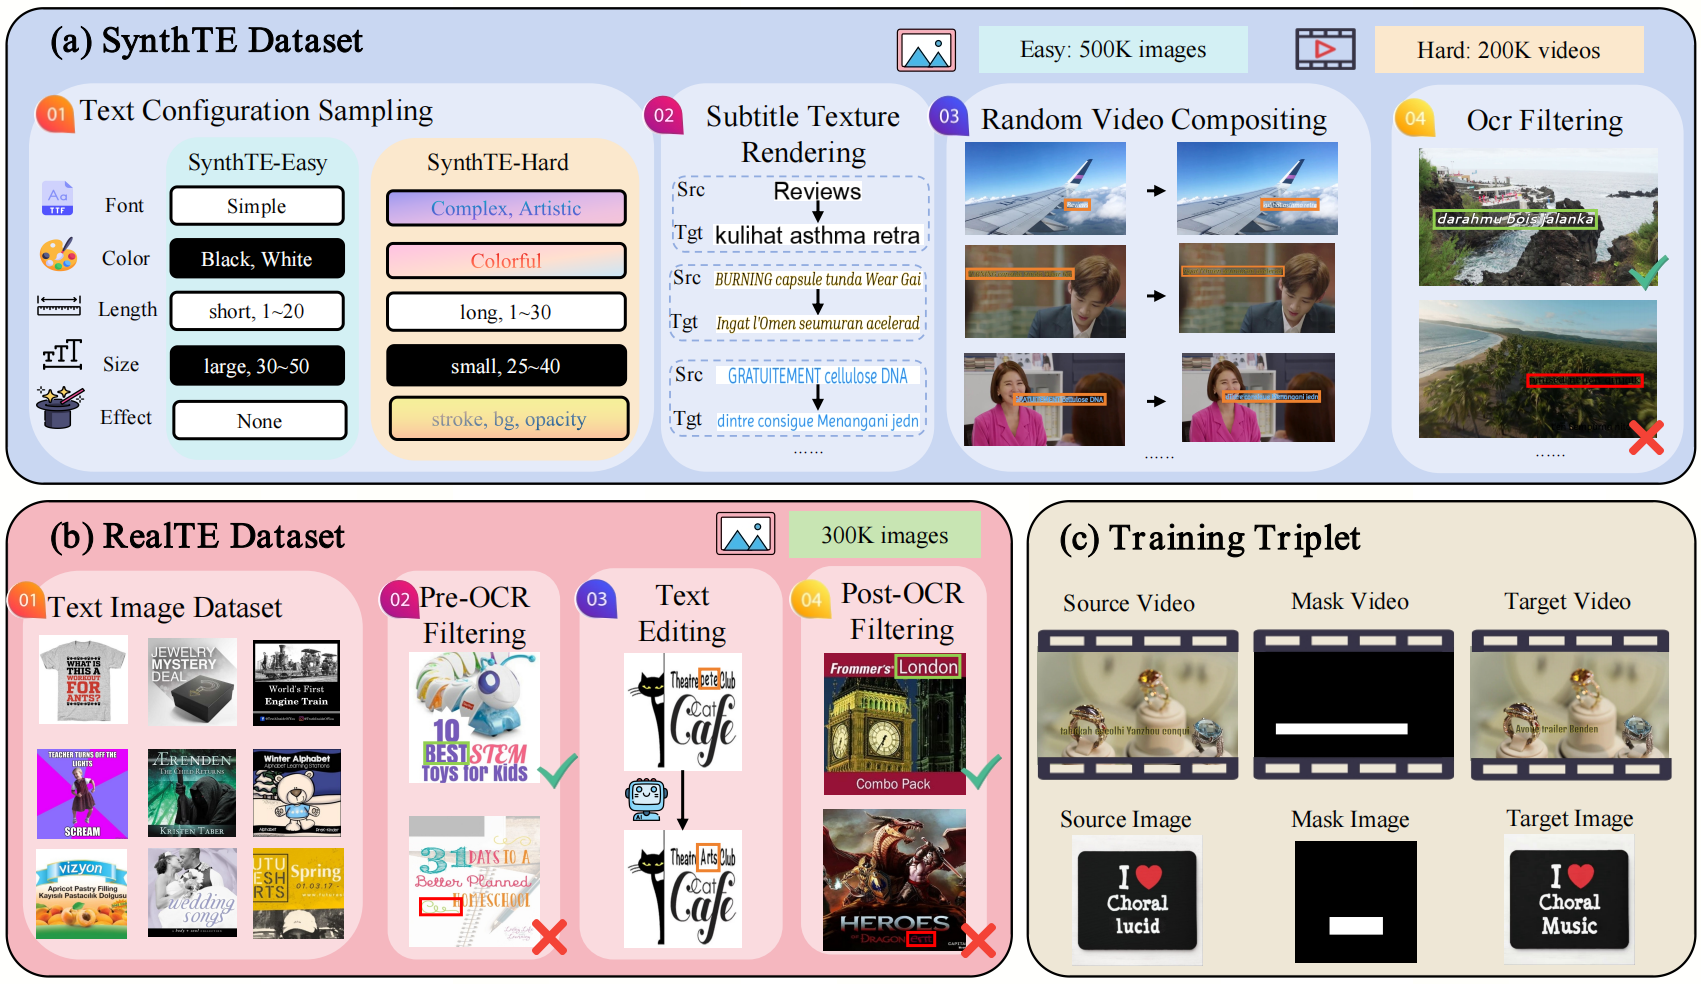
We construct SteerVTE-1M with two components.
- SynthTE synthesizes 500k image pairs (easy) and 200k video pairs (hard) using 1,933 fonts and OpenSora-Plan backgrounds.
- RealTE derives 300k image pairs from AnyWord-3M via OCR filtering, state-of-the-art editing, and style similarity verification.
Training Curriculum
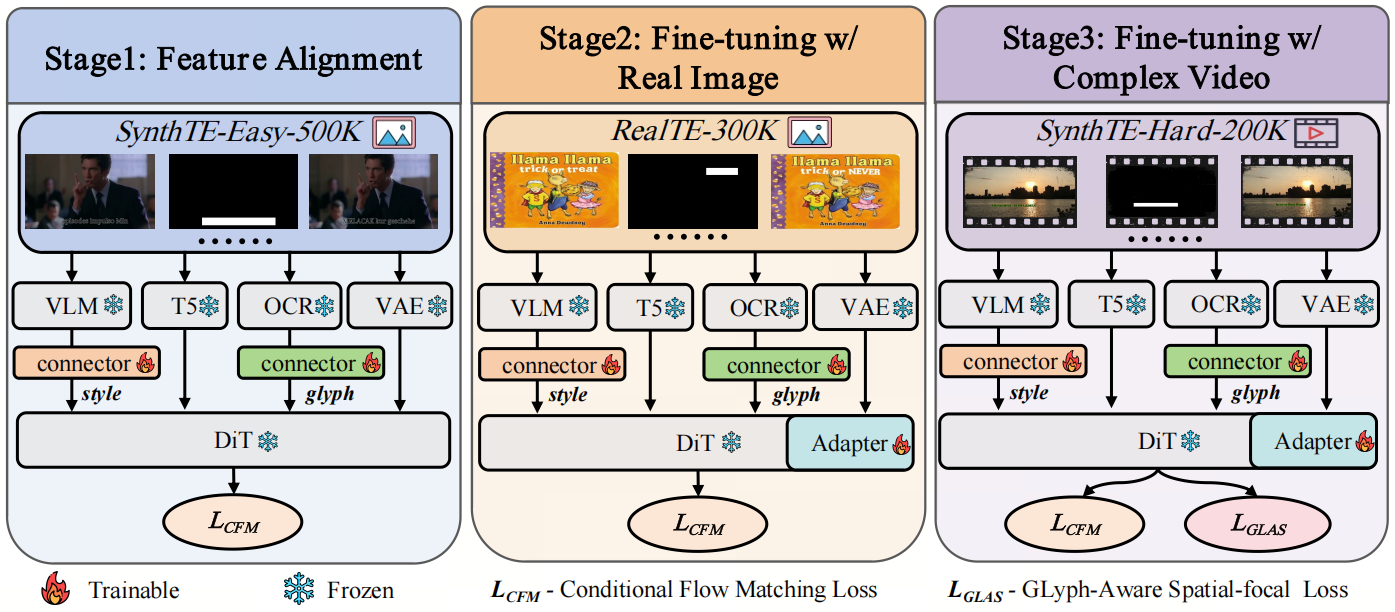
We train SteerVTE with a progressive three-stage curriculum.
- Stage 1: Feature Alignment. Trains only linear connectors on 500k synthetic images.
- Stage 2: In-the-Wild Fine-Tuning. Activates LoRAs and jointly optimizes on 300k real-world samples to bridge the synthetic-to-real gap.
- Stage 3: Temporal Fine-Tuning. Extends to 200k video clips with GLAS Loss to enforce kinematic coherence and glyph fidelity.